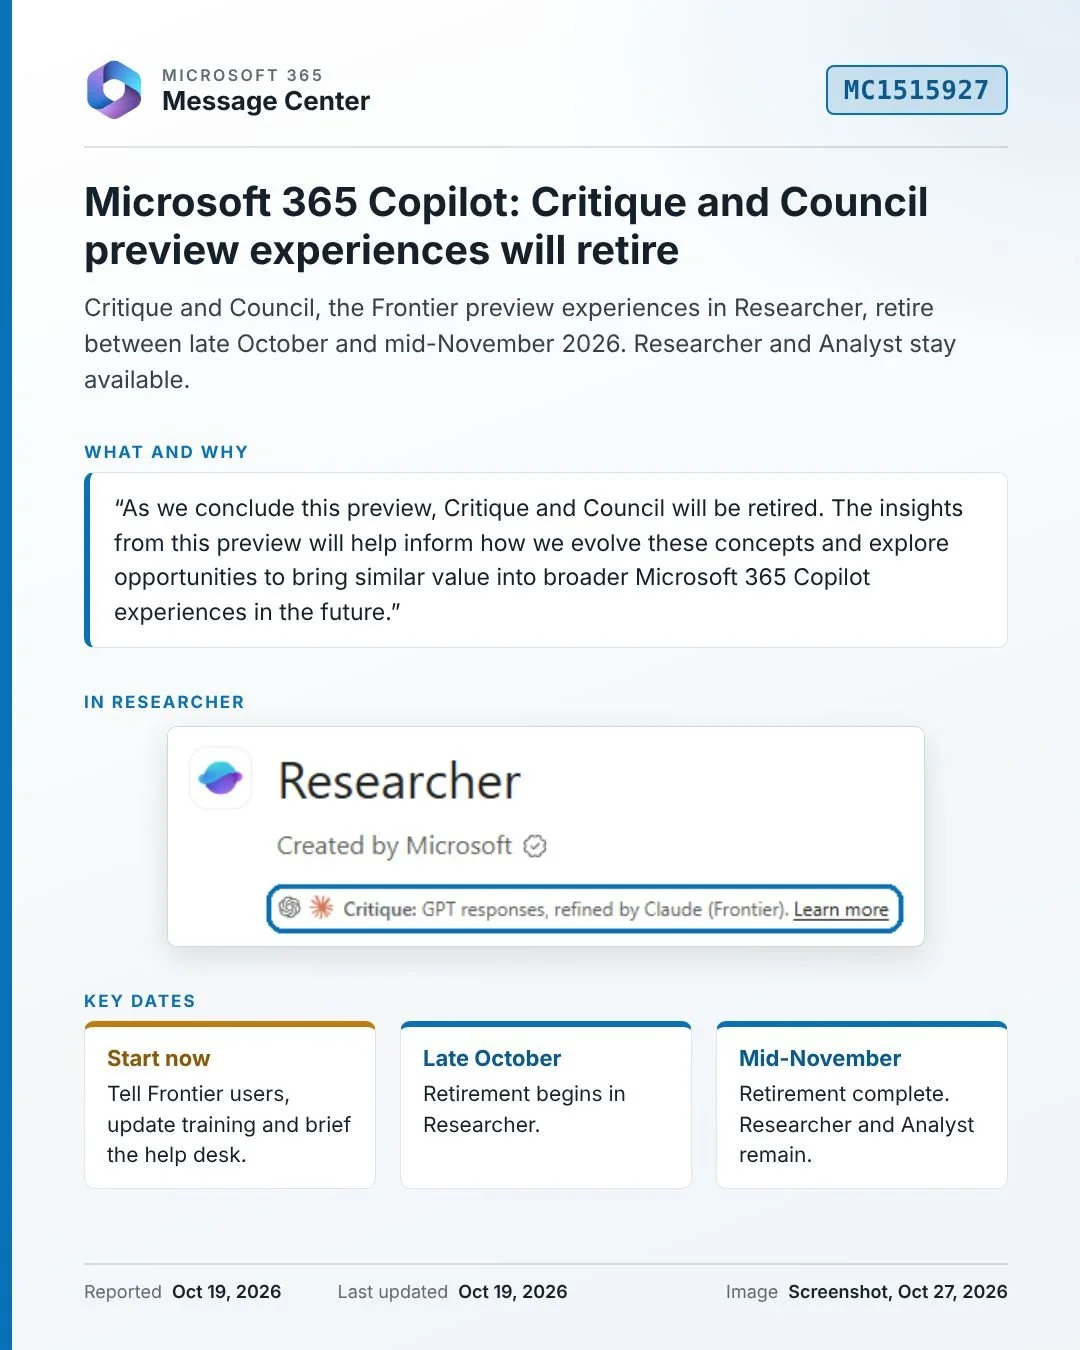
Critique and Council are being retired from Researcher. They arrived in April and never left Frontier, and with them goes one of the clearest examples in Copilot of technology turning "AI can make mistakes" disclaimers into something users can act on.
⠀
When these capabilities arrived in Researcher, they did reduce the verification workload. Instead of a generic warning that an output might be wrong, Researcher started pointing users toward the specific parts that deserved a closer look.
⠀
Model-checking-model is now a well-established way to reduce error, and it does help. But Microsoft's own benchmark for Critique showed its biggest gains in breadth of analysis and presentation quality, with a much smaller improvement in factual accuracy. And in the last year, this breadth is something individual frontier models have become much better at. What has also become clearer is that context plays an outsized role in how reliable an output is. Much of the recent development in Copilot is about getting that context in more reliably, from authoritative SharePoint sites to SharePoint knowledge bases and memory that draws on your work data.
⠀
But while these technical advancements might objectively improve quality and reliability, they do not eradicate the risk of error. And no matter how small that risk becomes, the verification fatigue problem remains. Even where AI-driven processes can be shown to deliver more reliable outputs than if the same work is done by humans, we tend to feel differently about the error risk they contain. We concede that humans will make mistakes while meaning to do their best, but we find it unacceptable for errors born from technology to negatively impact people.
⠀
A tool like Critique stood in the middle of this reality, focusing the human due diligence needed to mitigate AI error. Now that this tool is leaving, we might have AI capabilities that are more reliable overall, but we have less help to mitigate how we all feel about the errors that will inevitably still arise.
⠀
And that help never made it beyond Researcher. One of the main criticisms I hear from customers is how hard it is to build solid, reliable checks into everything AI produces. Microsoft now says it will "explore opportunities to bring similar value into broader Microsoft 365 Copilot experiences in the future", with no indication of how or when. In my view, this should be pretty high on the priority list.
⠀
With Critique gone, how are you helping your users decide which parts of an AI output deserve a second look?
First posted on Linkedin on 10/31/2026 → View Linkedin Post Here